Research output

Publications

Work in robot learning, reward modeling, world models, autonomous navigation, locomotion, and differentiable control.

Google Scholar

Preprints

2 works
arXiv 2026

Breaking Lock-In: Preserving Steerability under Low-Data VLA Post-Training

S. Huang, J. Shao, K. Wang, Q. Chen, J. Sun, Y. Guo, M. Schwager, J. Bohg

DeLock preserves visual grounding during low-data VLA post-training and uses test-time contrastive prompt guidance to retain steerability across novel concepts, spatial targets, and task configurations.

Preprint

SARM2: Multi-Task Stage Aware Reward Modeling for Self Improving Robotic Manipulation

Q. Chen, H. Zheng, J. Yu, S. Huang, J. Sun, K. Goldberg, C. Wen, P. Abbeel, Y. Shentu, P. Wu, M. Schwager

A multi-task, stage-aware reward modeling framework that produces dense rewards for long-horizon manipulation, enabling VLA policies to improve from low-cost autonomous rollouts.

Conferences

7 works
CoRL 2026

WARP-RM: A Warp-Augmented Relative Progress Reward Model for Data Curation

J. Yu*, A. Goldberg*, K. Kondap*, K. El-Refai*, E. Ransing, Q. Chen, M. Schwager, Y. Shentu, P. Wu, K. Goldberg

A self-supervised reward model that learns dense, signed relative progress from temporally warped robot demonstrations, enabling frame-level data curation without human annotations.

CoRL 2026

LEGS: Fine-Tuning Teleop-Free VLAs for Humanoid Loco-Manipulation in an Embodied Gaussian Splatting World

H. Kim, T. Chen, J. Sun, L. W. Osterberg, Q. Chen, K. Wang, M. Schwager

A teleoperation-free pipeline that procedurally generates photorealistic demonstrations in a physics-grounded 3D Gaussian Splatting simulator to fine-tune humanoid VLAs for zero-shot real-world deployment.
ICLR 2026

SARM: Stage-Aware Reward Modeling for Long Horizon Robot Manipulation

Q. Chen, J. Yu, M. Schwager, P. Abbeel, F. Shentu, P. Wu

A video-based reward modeling framework that derives progress signals from natural-language stage annotations for scalable long-horizon imitation learning.

CoRL 2025

ARCH: Hierarchical Hybrid Learning for Long-Horizon Contact-Rich Robotic Assembly

J. Sun, A. Curtis, Y. You, Y. Xu, M. Koehle, Q. Chen, S. Huang, L. Guibas, S. Chitta, M. Schwager, H. Li

A hierarchical framework combining imitation and reinforcement learning primitives with a high-level policy for precise, long-horizon robotic assembly.

CoRL 2025

ParticleFormer: A 3D Point Cloud World Model for Multi-Object, Multi-Material Robotic Manipulation

S. Huang, Q. Chen, X. Zhang, J. Sun, M. Schwager

A 3D world model trained directly from point clouds for dynamics prediction and model-based visuomotor control across objects and materials.

GRaD-Nav visual drone navigation
IROS 2025

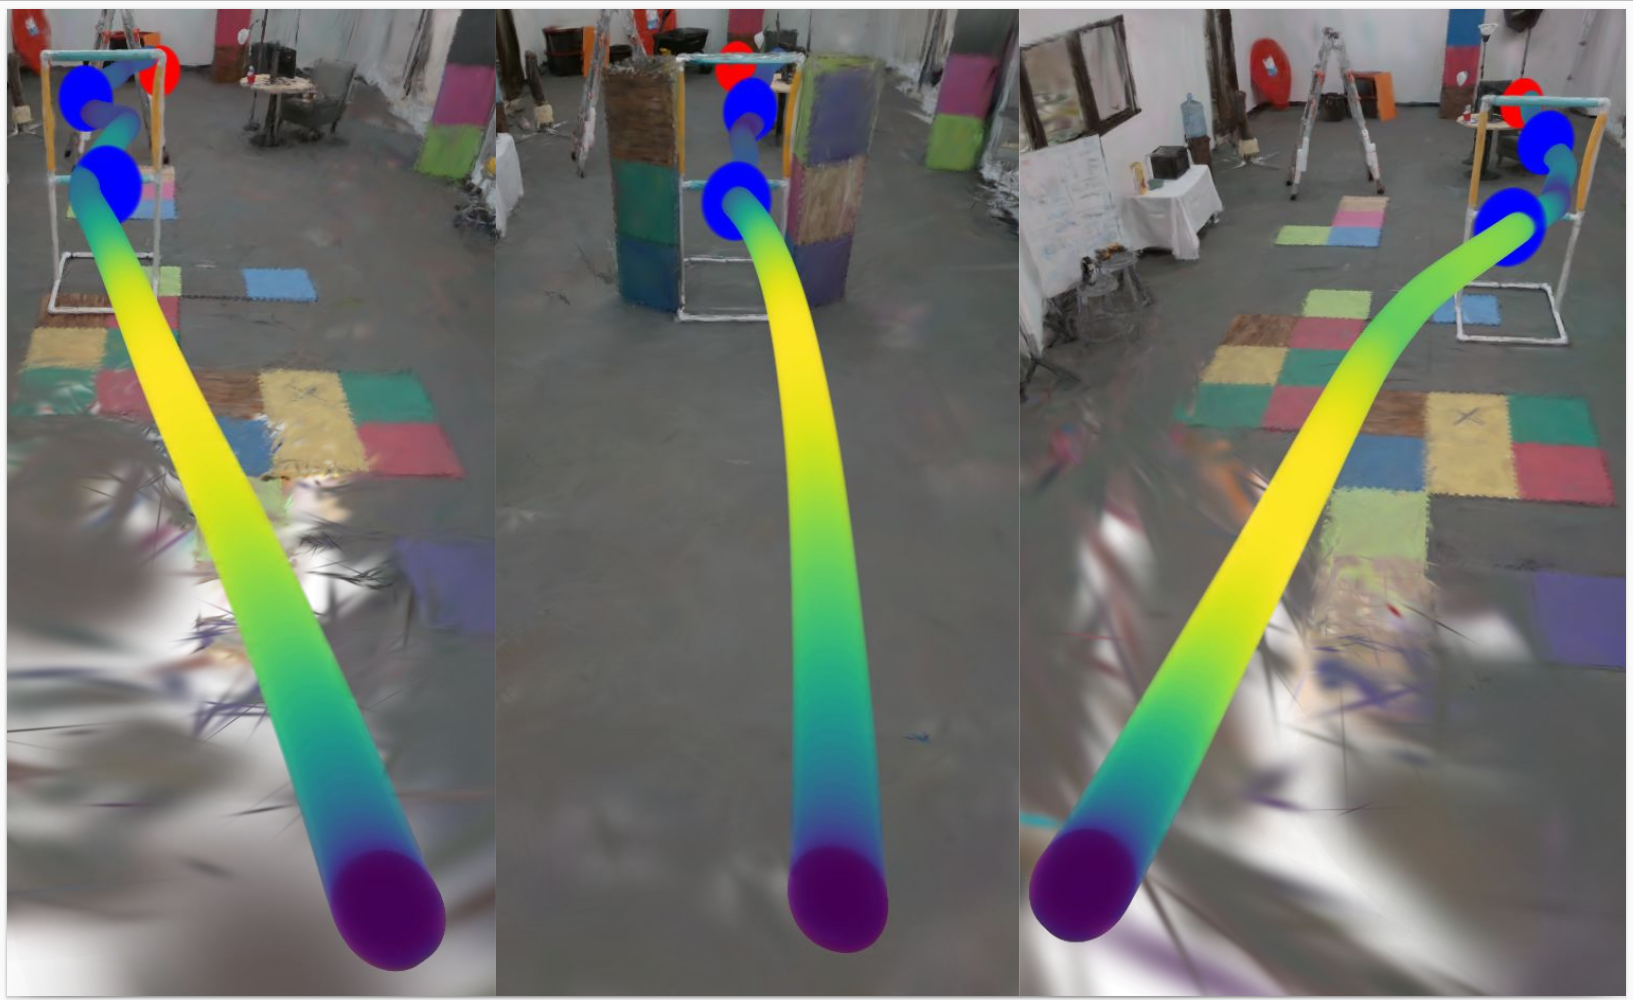
GRaD-Nav: Efficiently Learning Visual Drone Navigation with Gaussian Radiance Fields and Differentiable Dynamics

Q. Chen, J. Sun, N. Gao, J. Low, T. Chen, M. Schwager

A vision-based drone navigation framework using differentiable dynamics and Gaussian radiance fields for sample-efficient learning and robust generalization.

DiffTune bipedal locomotion
IROS 2025

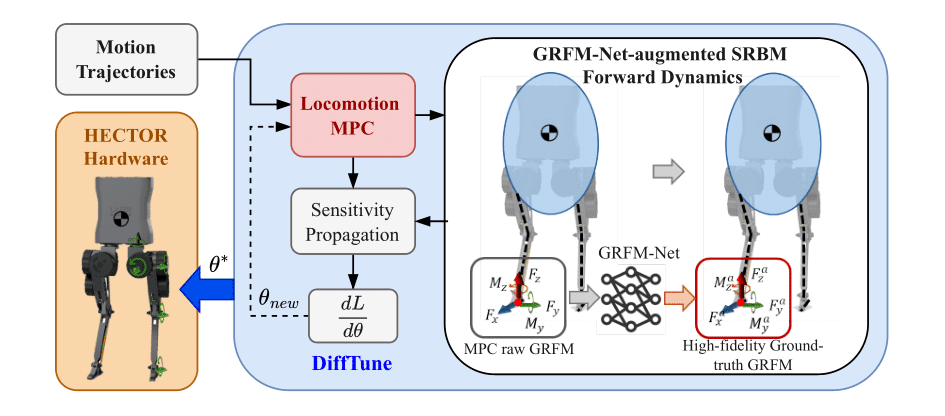
Autotuning Bipedal Locomotion MPC with GRFM-Net for Efficient Sim-to-Real Transfer

Q. Chen, J. Li, S. Cheng, N. Hovakimyan, Q. Nguyen

GRFM-Net and an MPC autotuning pipeline for robust and efficient sim-to-real bipedal locomotion transfer.

Journal articles

2 works
IEEE RA-L 2025 Best Paper Award · 5/1700

GRaD-Nav++: Vision-Language Model Enabled Visual Drone Navigation with Gaussian Radiance Fields and Differentiable Dynamics

Q. Chen, N. Gao, S. Huang, J. Low, T. Chen, J. Sun, M. Schwager

A lightweight onboard vision-language-action framework that trains in a 3D Gaussian Splatting simulator and follows natural-language drone commands in real time.
UAV trajectory optimization
IEEE RA-L 2023

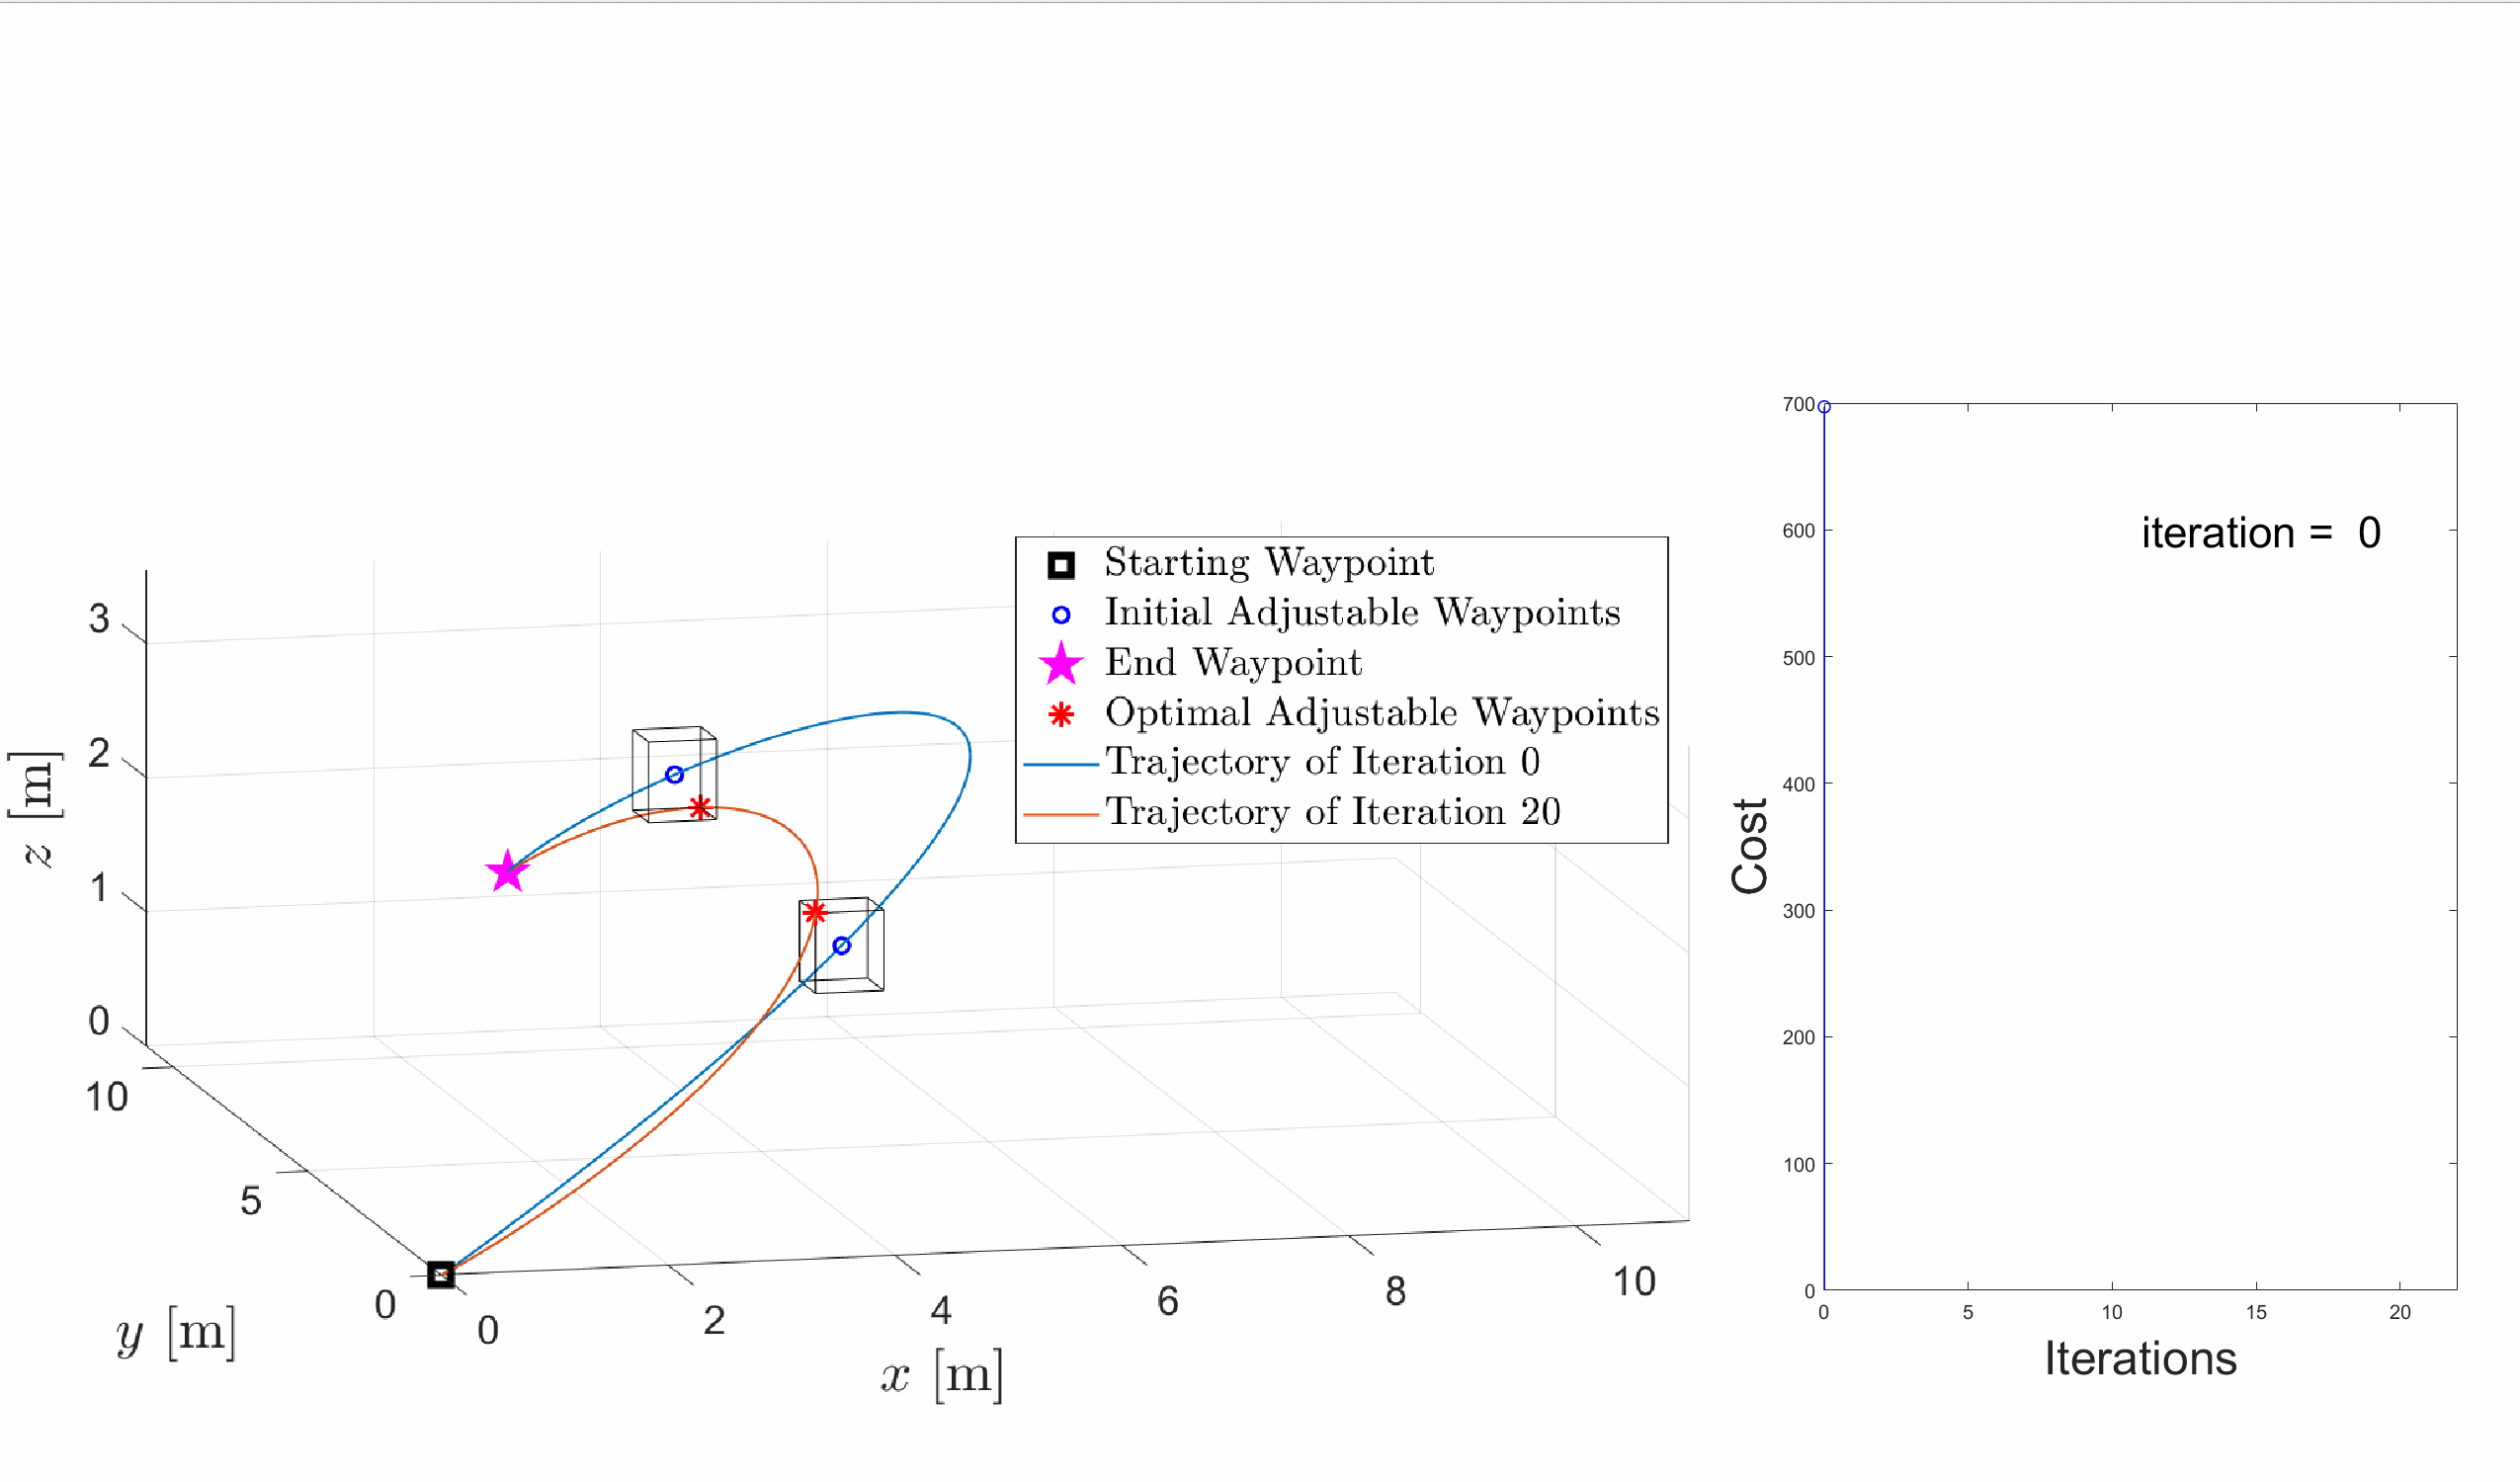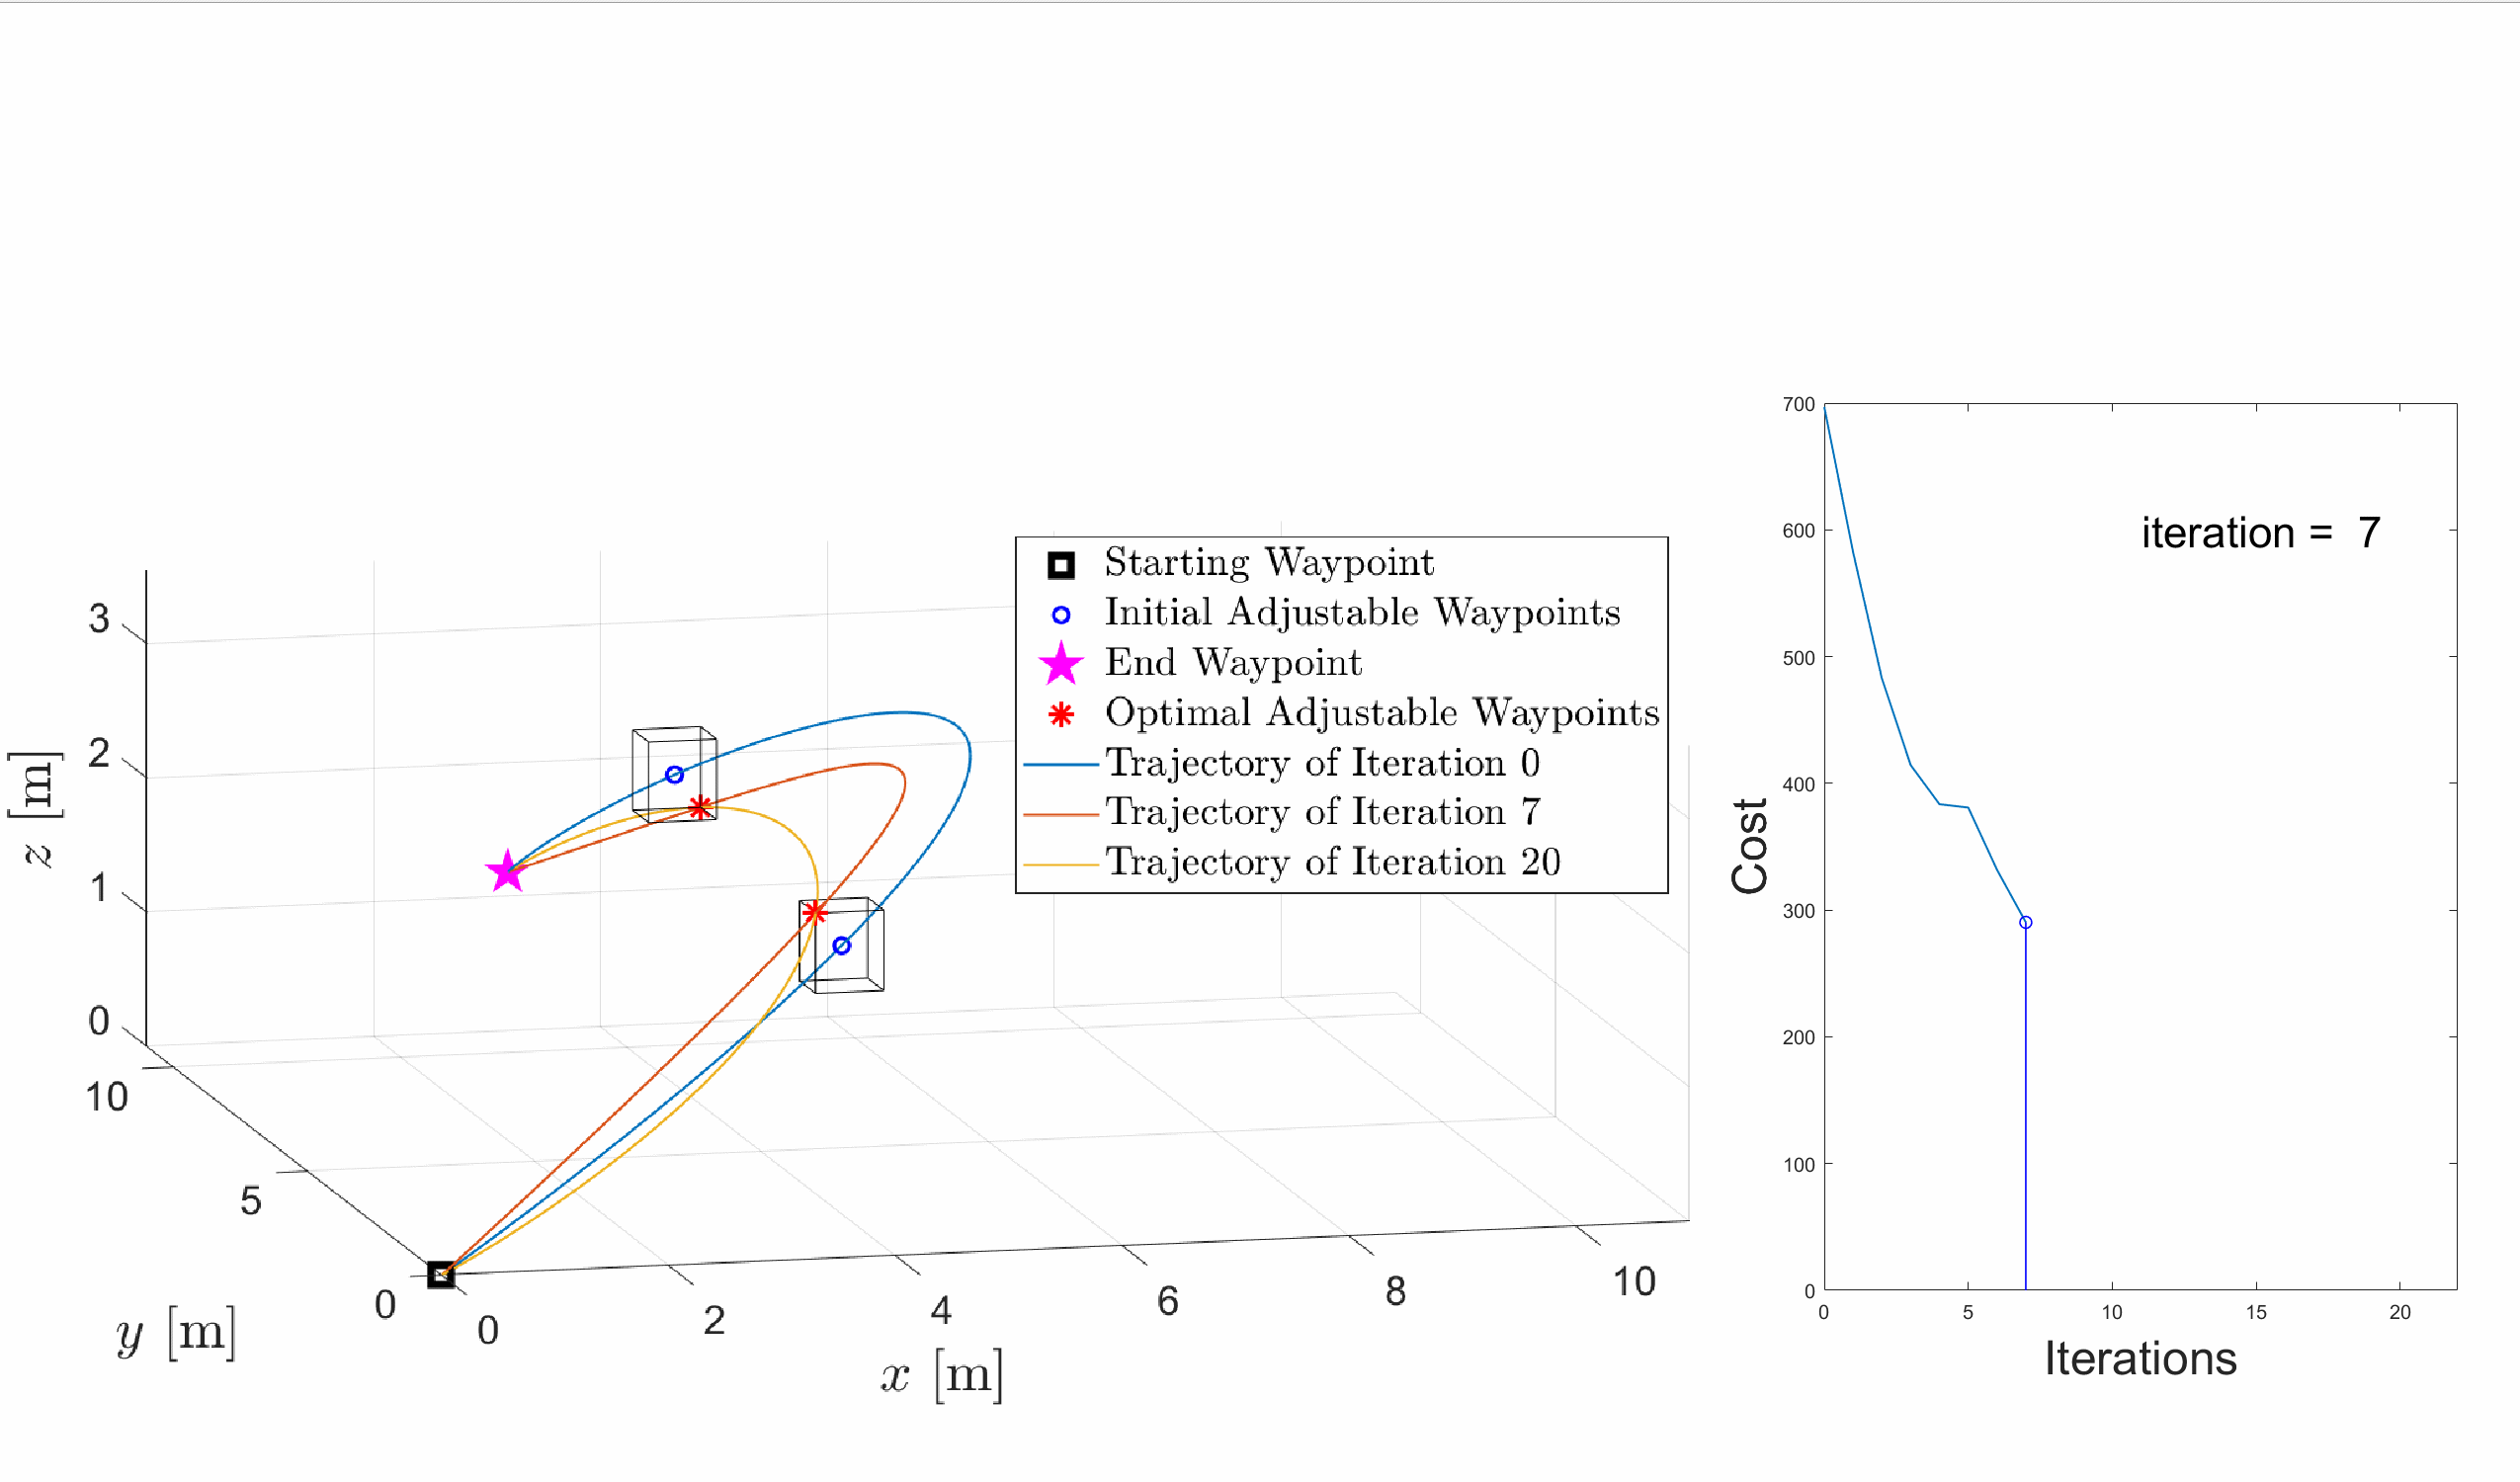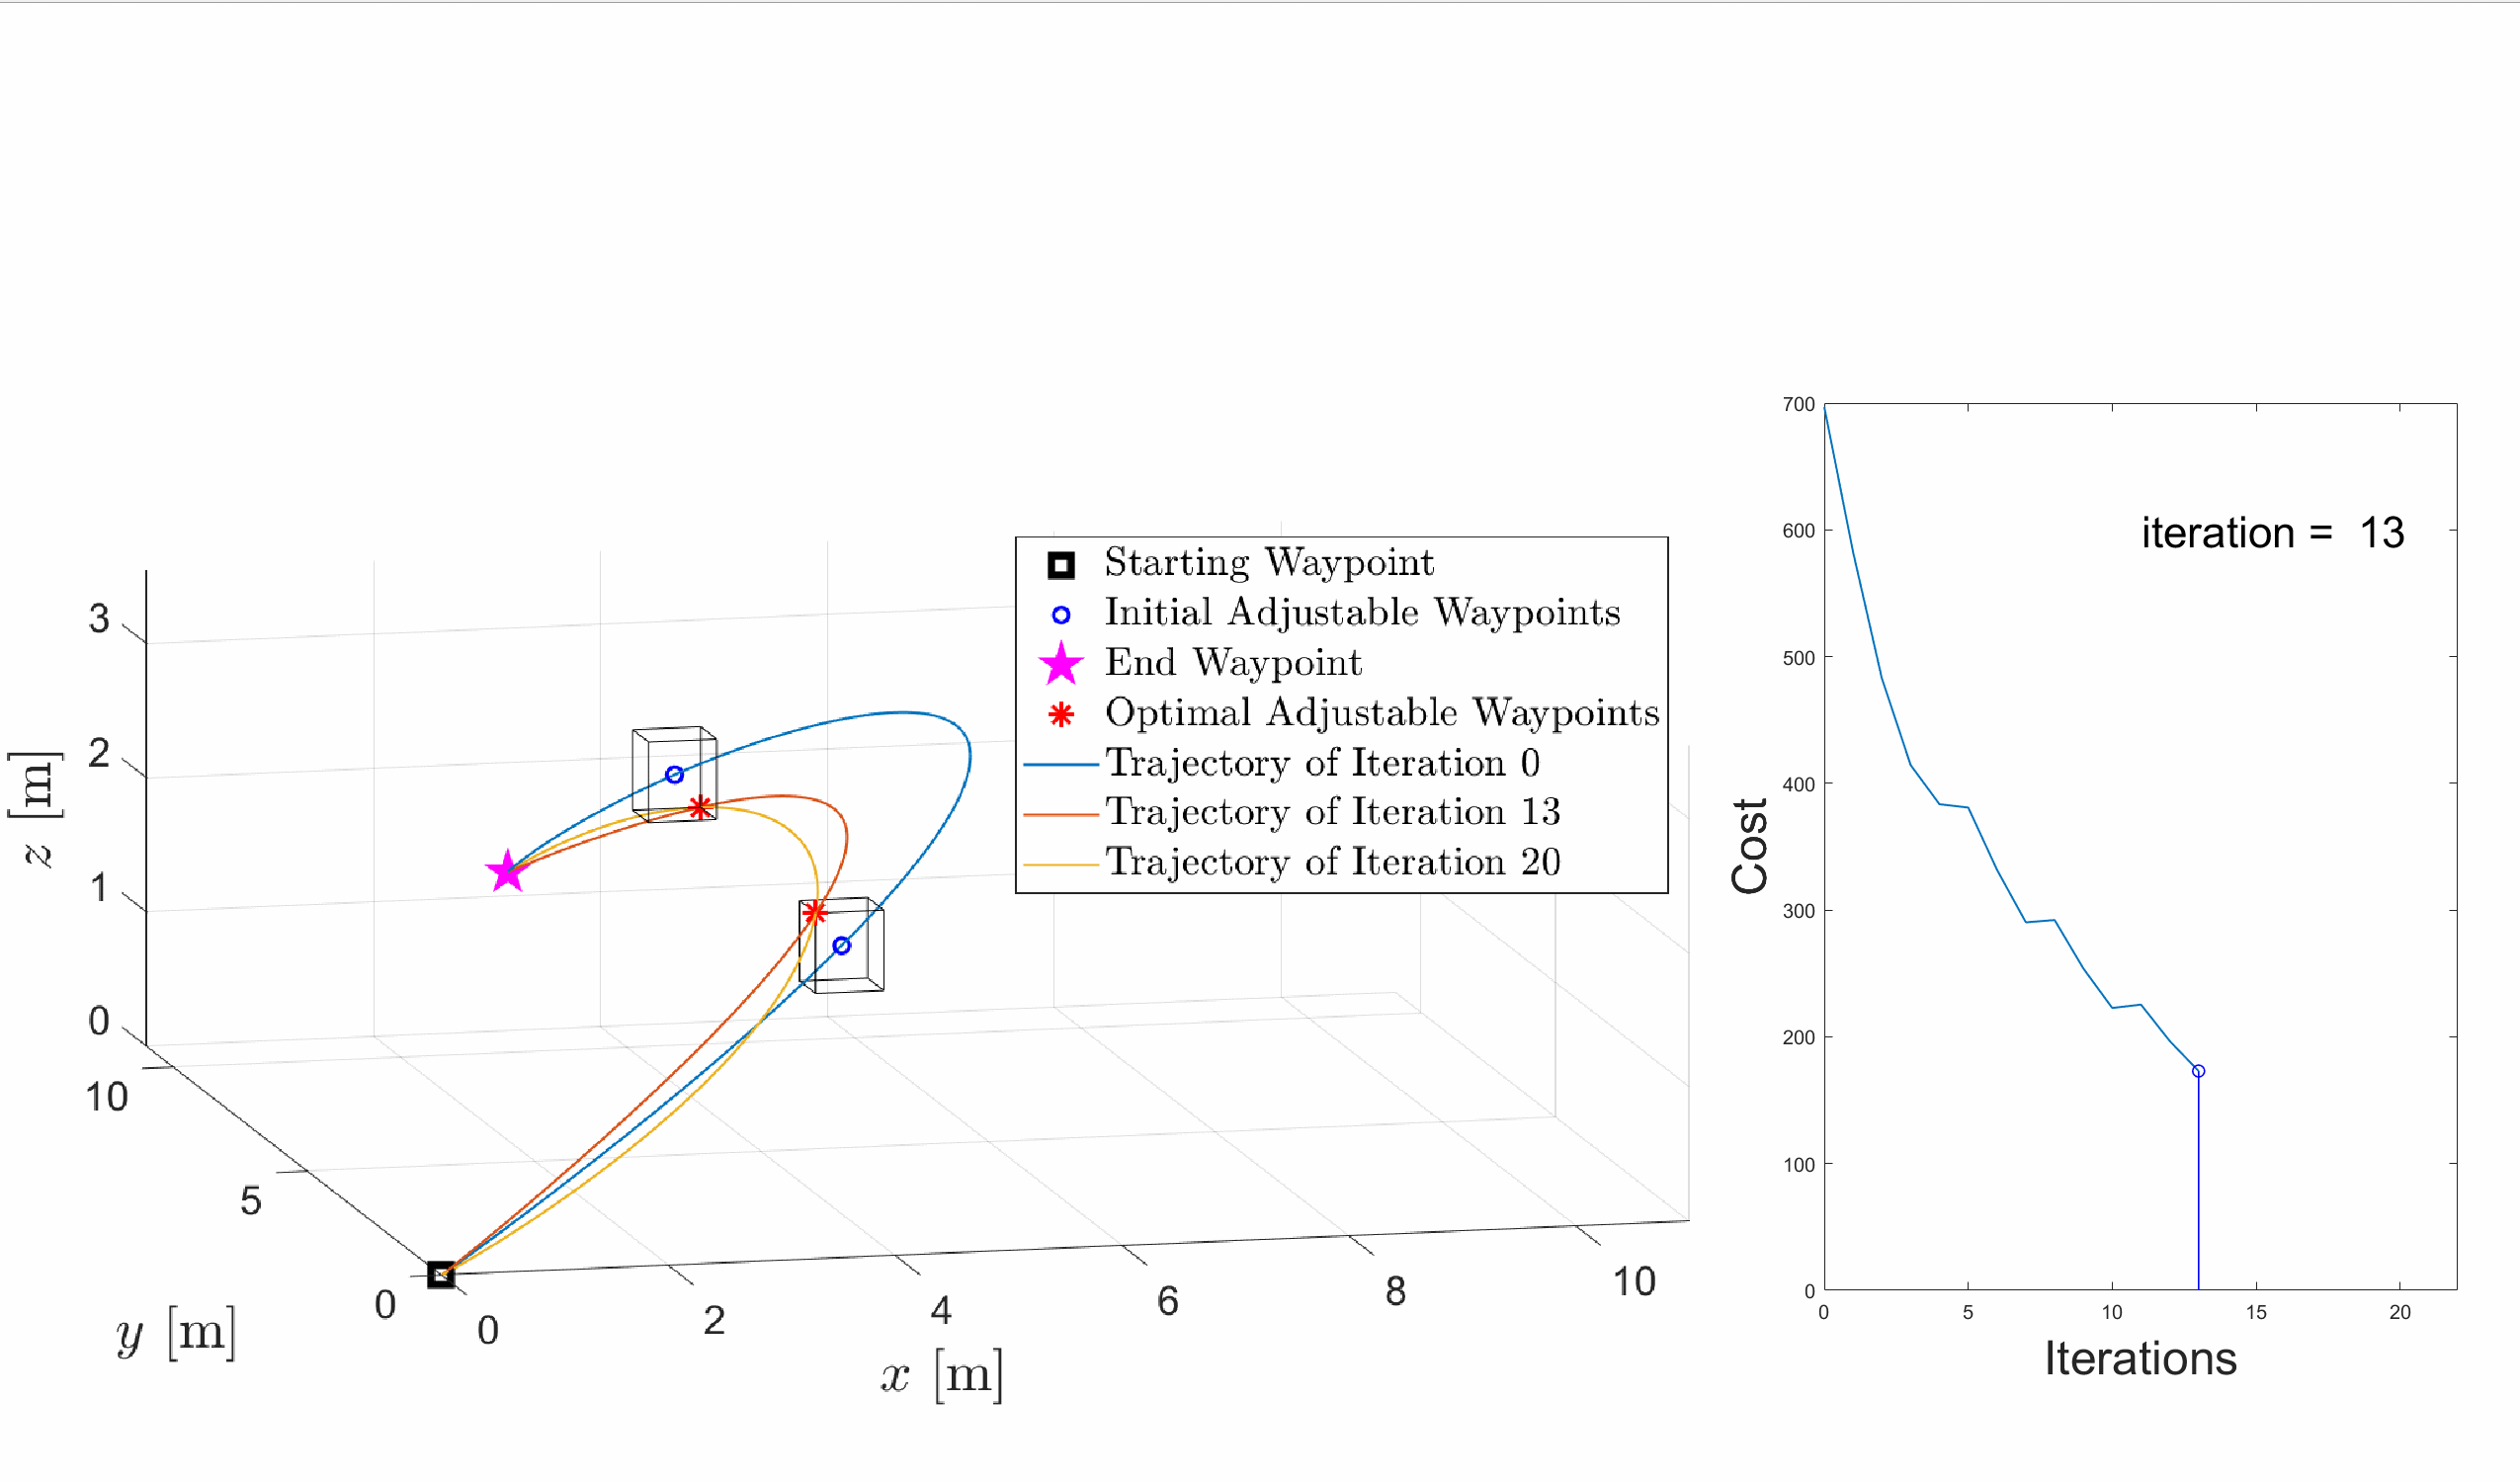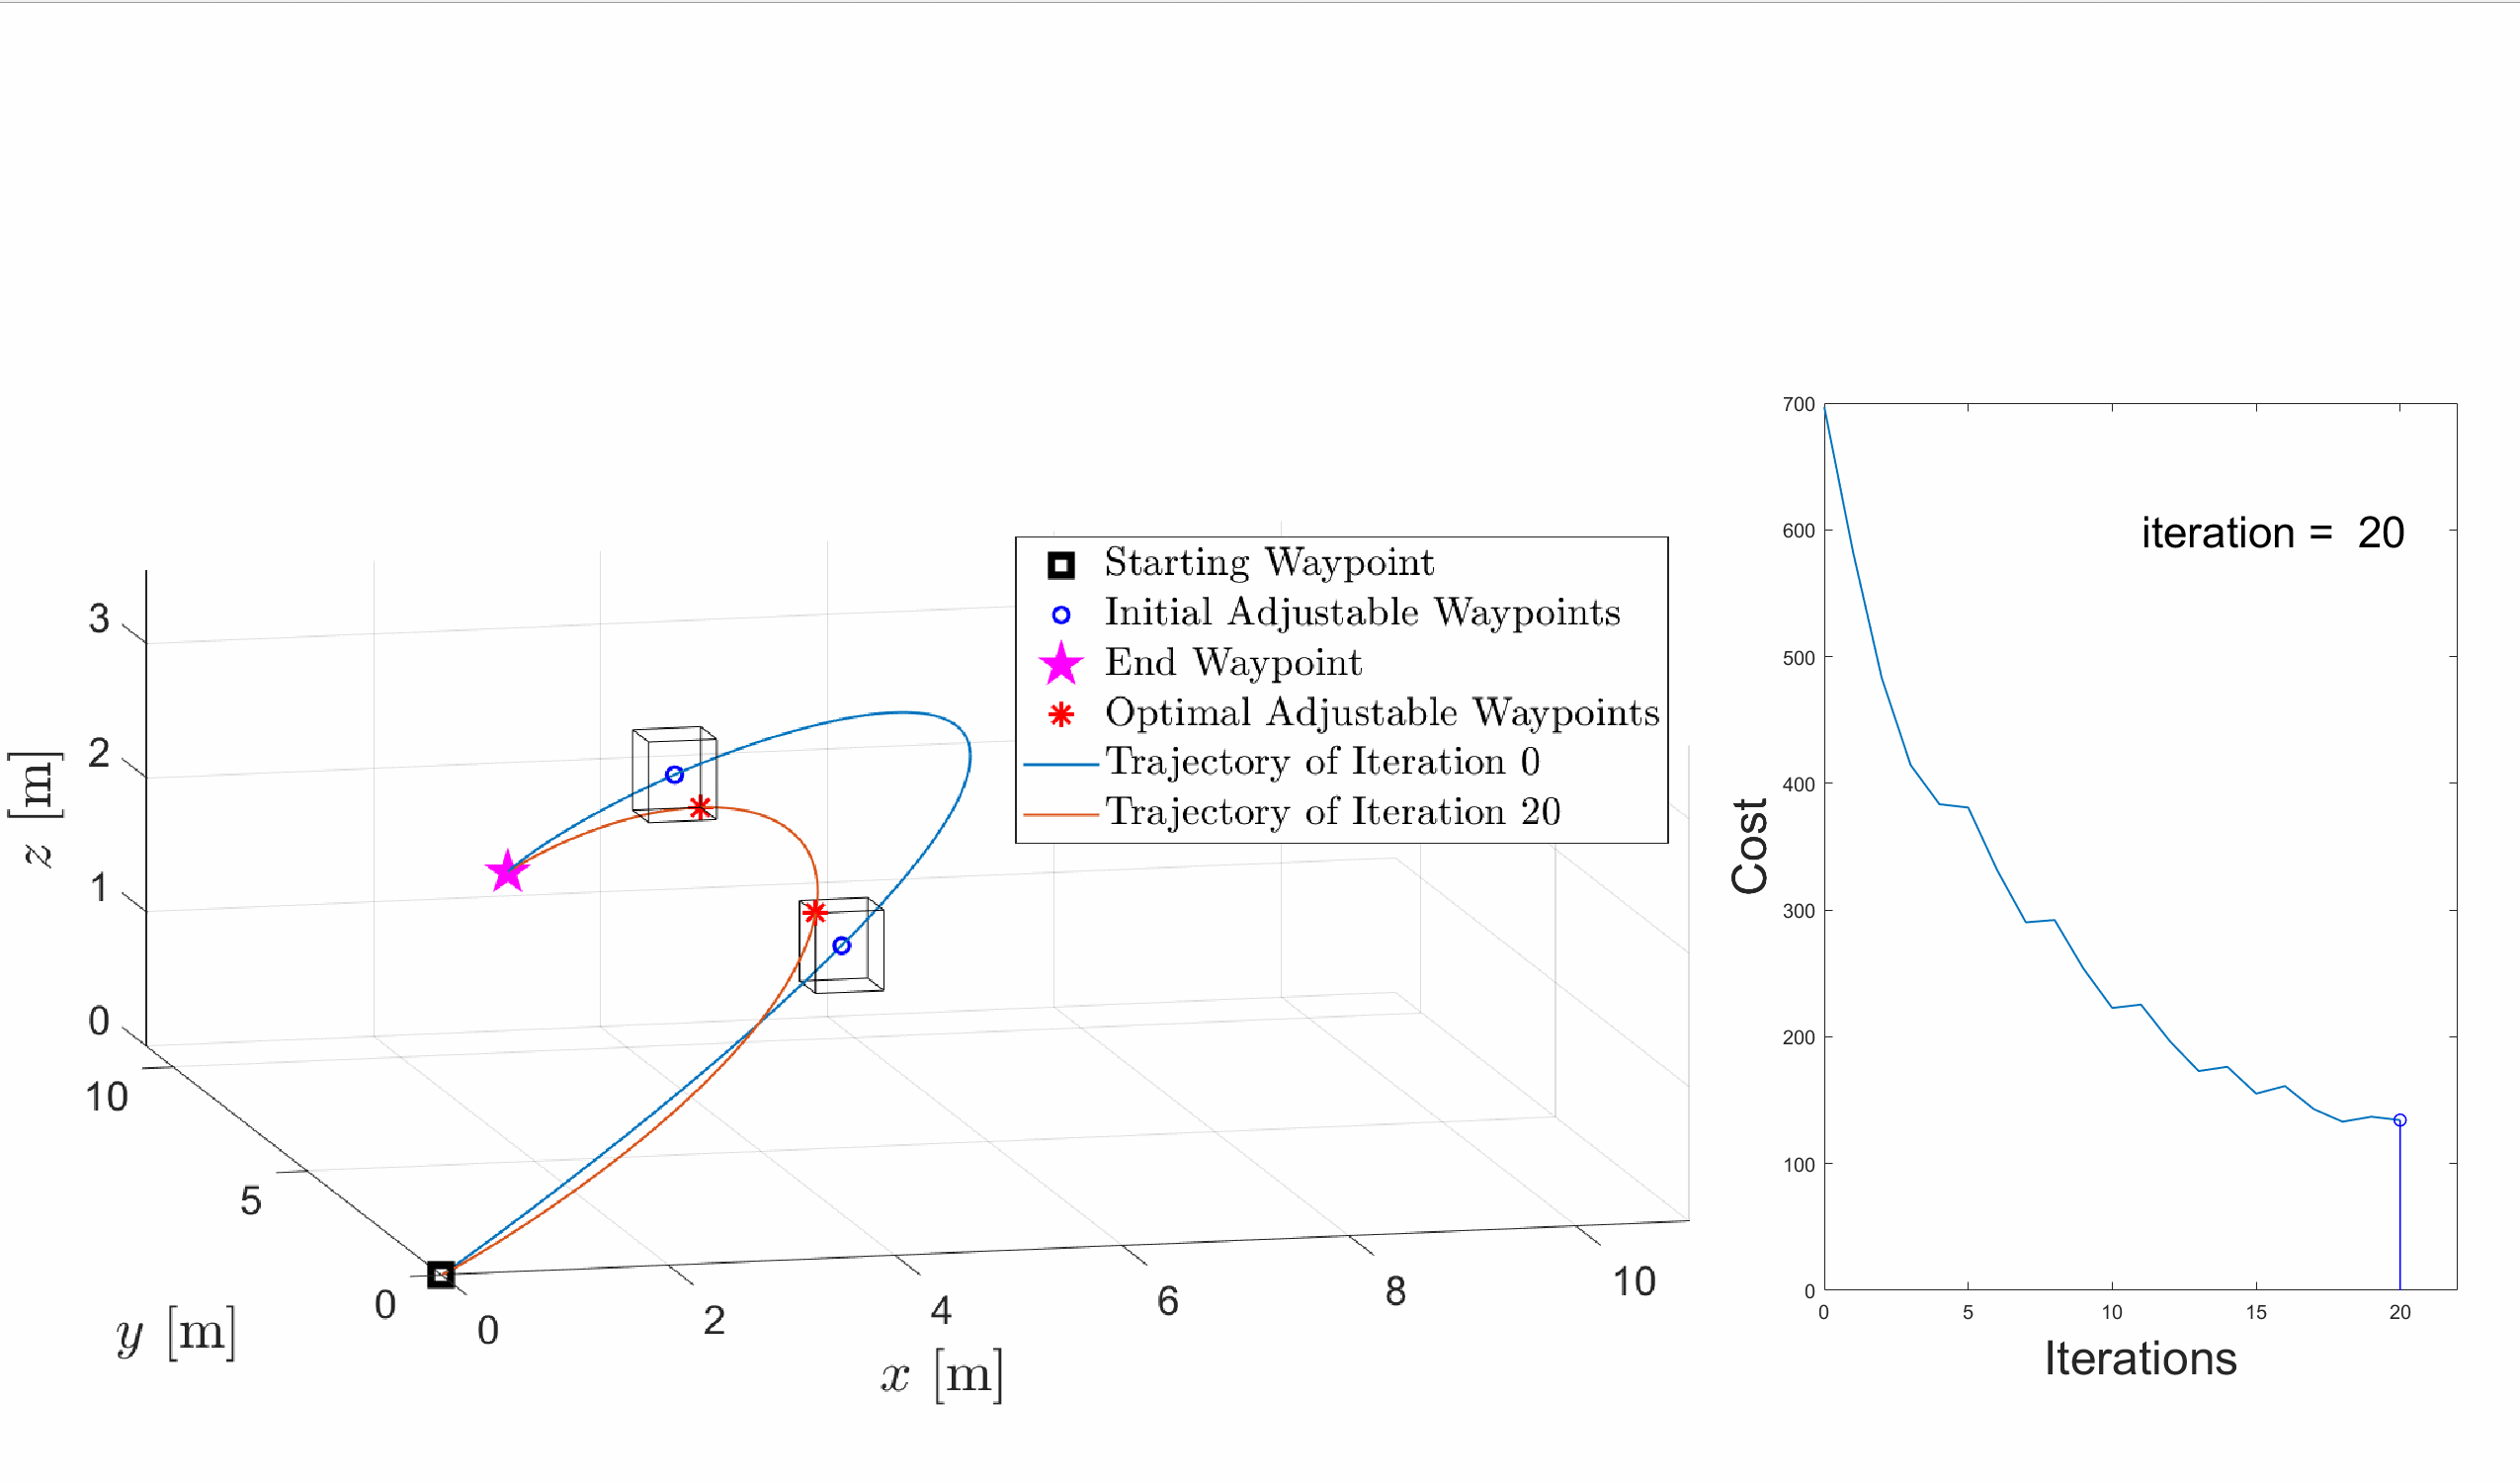
Simultaneous Spatial and Temporal Assignment for Fast UAV Trajectory Optimization using Bilevel Optimization

Q. Chen, S. Cheng, N. Hovakimyan

IEEE Robotics and Automation Letters, vol. 8, no. 6, pp. 3860–3867, 2023

A bilevel optimization framework that jointly assigns UAV waypoints in space and time for efficient navigation through constrained environments.